Resident of the world, traveling the road of life
69785 stories
·
22 followers

Pluralistic: Formalities (31 Oct 2026)

1 Comment and 2 Shares


Today's links

  • Formalities: When it comes to AI, the Copyright Office is restoring copyright to its proper status, as something you have to work to get.
  • Hey look at this: Delights to delectate.
  • Object permanence: GWB x martial law; Li'l Sparky; Dueling Starbuckses; Microsoft buys Skype (does fuckery); Bieber v SOPA; SOPA is the worst; Snowden x rule of law; "Laserwriter II"; Russia v DST; Class war funnies; Minnesota's miracle; Icelandic women v sexism; Image analogies; Aussie DMCA ratfucked; "Authorised Domain"; Sales tax is regressive; Prince Charles's secret veto; Wells Fargo blackballed workers for refusing to crime; Poe read by Vincent Price and Basil Rathbone; Put it back!; The internet was made for privacy.
  • Upcoming appearances: Kilkenny, Courtenay, Vancouver, Folkestone, Oxford, Sheffield, Virtual, Oxford, Montreal.
  • Recent appearances: Where I've been.
  • Latest books: You keep readin' em, I'll keep writin' 'em.
  • Upcoming books: Like I said, I'll keep writin' 'em.
  • Colophon: All the rest.


A humanoid robot with blue skin pocked with transparent patches that show circuit boards beneath. Its eyes are yellow copyright symbols. It is admiring its reflection in a mirror supported by a gold robot. The reflection of the robot has red x's in its eyes instead of copyright symbols.

Formalities (permalink)

It's not often that I find myself on the same side as the US Copyright Office. In fact, I think this is the first time in 25 years that I've found myself cheering on the office's official actions as good for art and good for free expression, taking the side of creative workers over our bosses.

The source of our miraculous accord: the US Copyright Office's position on AI. The CO has taken the (entirely correct) position that copyright law exists to incentivize human acts of creative expression, which means that only works of human authorship are eligible for copyright.

This isn't a controversial position within legal circles. But for media executives, this is shocking; absurd, even. This gap between the industrial and the legal understanding of copyright comes from a fundamental difference over the evocatively named legal doctrine of "sweat of the brow."

"Sweat of the brow" is fundamental to a correct legal understanding of copyright. Copyright rewards and protects creativity but it does not protect hard work. You can labor for ten years over a phone book listing the numbers of every person in a town and (as a collection of uncopyrightable facts) it will receive no protection at all. Zero. Zilch. Anyone can copy and sell that phone book:

https://en.wikipedia.org/wiki/Feist_Publications,_Inc._v._Rural_Telephone_Service_Co.

Copyright law doesn't care if you slaved over that collection of facts, if you missed sleep and your kids' little league games to realize your grand vision. Copyright law doesn't care if you plowed every cent into it, remortgaging your home and cashing in your (already resentful) kids' college funds.

But: if you dash off a haiku in ten seconds while sitting on the toilet, shove it into your pocket and forget about it, and then your (still resentful) kids discover that crumpled haiku after your (highly suspicious) death, your kids will be able to claim a full 70 years' worth of copyright over that forgotten triviality (the term of copyright for works of human authorship is life plus 70 years).

This is the uncontroversial and universally accepted legal understanding of copyright: all the copyright in the world for creative acts, no copyright at all for mere acts of labor. The "sweat of the brow" has nothing to do with a work's eligibility for copyright.

But no media boss believes this. For media bosses, copyright is a pseudo-property† right, designed and operated to protect their bottom line. The point of copyright isn't to incentivize creativity, but rather investment.

† Or not-so-pseudo

There's obviously a relationship between creative acts and acts of investment, but it's possible to create without investment (see: your haiku) and it's possible to invest without creativity (see: your phone book).

And once again, the creativity that copyright protects is human creativity. This is a lesson that David Slater learned the hard way. Slater is a professional wildlife photographer and amateur monkey-trainer who combined his interests by teaching Celebes crested macaque monkeys to take selfies. But when Slater published a monkey's selfie others copied and distributed the image without his permission, on the (entirely legally correct) basis that monkeys are not humans, and that means that works created by monkeys don't get a copyright. This was also the Copyright Office's position, and the position of the Ninth Circuit Court of Appeals:

https://en.wikipedia.org/wiki/Monkey_selfie_copyright_dispute

This is the basis for the US Copyright Office's repeated decision to refuse to extend copyright to AI-generated works. An algorithm is even less human than a monkey, so if you can't get copyright over a monkey selfie, you definitely can't copyright your chatbot's slop. The US Copyright Office has successfully defended this position in multiple courts, triumphing over plaintiffs who were so persistent that they even got the Supreme Court to weigh in on the issue (the Supremes decided the case didn't warrant their attention):

https://pluralistic.net/2026/03/03/its-a-trap-2/#inheres-at-the-moment-of-fixation

AI slop isn't copyrightable, but there can be copyrightable elements in an AI-generated image. The most obvious element is the prompt. So long as your prompt contains some quantum of creativity (e.g. "Make me a beautiful flower whose loveliness is reminiscent of a newborn baby", but not "make me a beautiful flower"), that prompt is copyrightable. That means you can use copyright to challenge others' rights to present the same prompt to a chatbot. But while the prompt can be copyrighted, the image it gives rise to isn't. So you can spend a month iteratively refining your prompt, consuming all your town's water along with 200,000 gallons of diesel and that prompt will be yours for your life plus 70 years, but the image it generates is in the public domain, and anyone can copy it, sell it or give it away.

There are other ways that copyright can find its way into AI-generated material. You can make creative edits to it: if you output a slop novel and rewrite various sentences (providing those rewrites involve some creativity and not just mechanical corrections or word substitutions), then the edited sentences become copyrighted works, even though all the rest of the text remains uncopyrightable.

You can also get a "thin" copyright through selection. If you get your chatbot to output many images based on your prompt and choose your favorite, your selection can confer a tiny bit of copyright over that creative act of selection, but it will be harder to defend than even the other (attenuated and highly specific) forms of copyright.

Now, perhaps you've spotted an administrative problem lurking in this turn of events. How can someone else know what part of a work is AI-generated (and thus in the public domain) and which parts are human-edited/contributed (and thus copyrighted)? Just as importantly, how can you prove which parts of your work are not AI-generated and thus eligible for copyright protection.

This gets especially gnarly when you're dealing with complex media. In an animation, an AI might do the rigging and movement for a human-created sprite. The sprite is copyrightable, but its movements aren't. That would mean that I could remap your sprite's movements onto a different sprite without infringing your copyright. Or say the sprite and its movements are human created (and thus copyrighted), but the backgrounds are procedurally generated? I could take those backgrounds and put new animations overtop of them.

The simplest, most reliable way to ensure the works you invest in are fully and entirely eligible for copyright is to just use humans for the whole project. Declare a "no-AI policy," and hire human artists to produce the works you hope to sell. Monitor their activity to ensure they're not using AI. Keep good records.

Now, as much as I like the idea that we've arrived at a copyright law that insists that a company can only get exclusive rights to its products by paying human artists to make them from end-to-end, I don't think that's likely to be the way it shakes out, but that doesn't mean that this is a wash for artists.

The reality is that copyright claims are always "fact-intensive inquiries" that are expensive to litigate and difficult to adjudicate. It's completely normal for copyright lawsuits to turn on documentary evidence gleaned from fragmentary records. This is simply intrinsic to copyright, because copyright is a doctrine that requires judges to assess whether things are "creative" and "original" as though these were freestanding categories that everyone could agree upon.

Of course, the rules of copyright can make this harder or easier. One way in which the rules make deciding copyright cases much, much harder is copyright's broad prohibition on "formalities" ("formalities" is how copyright wonks refer to "red tape" or "paperwork"). For nearly all of American history, copyright ran on a key formality: deposit, registration and notice.

To secure a copyright for a new work, an artist (or their employer) had to send a copy of that work to the Library of Congress (deposit), along with paperwork detailing the claim of authorship (who made this, what parts of it did they make) (registration) and they had to display a copyright notice that told you who held the copyright to every work that was registered (notice). Both the filing and the notice required careful attention and precision, and screwing either one up could result in your losing your copyright. It's an open secret among copyright scholars that Walt Disney screwed this up with the first Mickey cartoons, meaning they've been in the public domain since their release:

https://web.archive.org/web/20080725055415/http:/homepages.law.asu.edu/~dkarjala/opposingcopyrightextension/publicdomain/HedenkampFreeMickeyMouseVaSp&E(2003).htm

This system of copyright formalities meant that you could always tell whether a work was copyrighted, you could always find out who claimed the copyright over it, and which parts of the work were claimed under copyright and under what basis. What's more, formalities created the Library of Congress, since the LoC acted as America's "copyright deposit" library, holding deposit copies of every work that had ever been issued a US copyright.

The US system of formalities was descended from the English system, in which the Stationers' Guild used a copyright registry to establish who had the rights to which books. But there were competing copyright systems, notably the "continental" system that was codified through the Berne Convention, a copyright treaty drafted by Victor Hugo (yes, that Victor Hugo).

Among other things, the Berne Convention abolished formalities. Much of the world adopted Berne, but the US held out until 1976. With the 1976 Copyright Act, Congress brought the US into compliance with Berne, abolishing formalities in the USA. As a compromise, the 1976 Act requires US authors to register their copyrights in order to obtain "statutory damages" (up to $150,000 per work). That's a pretty good incentive, but even with that incentive, the vast majority – far in excess of 99.999999999999999999999999999999999999999% – of all copyrighted works are not registered with the Copyright Office. They are born copyrighted from the moment they are "fixed in a tangible medium" until 70 years after their authors die. But without registration, you can't know when that copyright clock started ticking because you have no way to verify who the author of the work is. This not only makes it incredibly difficult to establish the copyright status of nearly every copyrighted work, but it also means that in nearly every case, you can't readily determine who you should approach if you want to pay them for a copyright license.

Abolishing formalities has created a universe of orphan works: everything from napkin doodles to kindergartners' finger paintings to message board posts. Within that universe is a kind of gaseous cloud that, if condensed, would come out to an infinitesimal planetoid, representing the entirety of commercial works whose authors give a damn about their copyright status. It's a bad, bad system.

This system doesn't do away with the need to keep careful records: like I said, copyright disputes usually require the close examination of documentary evidence. What formality abolition accomplished was the destruction of the regular system of record-keeping: rather than having a standard, universally agreed-upon way to determine the status and resolve disputes about a copyrighted work, now we have the scattershot, incoherent system that makes copyright disputes far more likely (because no one knows who to approach for copyright licenses) and far more difficult to resolve (because there's no registry of copyrighted works).

Which brings me back to the question of AI and copyright. If a firm uses some AI in its work, it's going to need to document that very carefully. Firms that don't keep very close track of the elements of their products that come from AI will have a far harder time defending their commercial interests.

Basically, we're about to recreate formalities, but managed by the private sector. To the extent that companies use AI in their work, they are going to have to track every pixel and every word and every note that is output by an AI system, and which parts were added or edited by humans after creation.

That means that companies that want to protect their commercial interests aren't just going to get more protection based on how much work they get humans to do; they're also going to have to treat copyright's government-enforceable monopoly over expressive speech with the gravitas it deserves: not something you get automatically, but something you have to do real administrative work for.


Hey look at this (permalink)


A shelf of leatherbound history books with a gilt-stamped series title, 'The World's Famous Events.'

Object permanence (permalink)

#25yrsago Slushpiles v anthrax https://memex.craphound.com/2001/10/29/some-publishers-have-instituted-new/

#25yrsago Image analogies https://mrl.cs.nyu.edu/projects/image-analogies/

#25yrsago Cleaning the Fucking Kitchen for Dummies https://web.archive.org/web/20011007082222/https://www.fridgemagnet.org.uk/kitchen.html

#20yrsago Last minute changes snuck into Aussie DMCA https://web.archive.org/web/20061104133320/https://www.eff.org/deeplinks/archives/004975.php

#20yrsago Creative Commons 3.0 license drafts published https://creativecommons.org/2006/10/30/version30revisedlicensedrafts/

#20yrsago Bush legalizes martial law https://politics.slashdot.org/story/06/10/28/1934208/bush-signs-bill-enabling-martial-law

#20yrsago No blogging allowed at “consumer generated media” conference https://web.archive.org/web/20061108055635/http://gregverdino.typepad.com/greg_verdinos_blog/2006/10/social_media_fi.html

#20yrsago Li'l Sparky: miniature 9V electric chair https://www.flickr.com/photos/84221353@N00/281833134/in/pool-make/

#20yrsago New Starbucks stores to open across the street from each other https://www.spokesman.com/stories/2006/oct/29/starbucks-buzzes-along-with-expansion/

#15yrsago HOWTO defend yourself against tear-gas https://web.archive.org/web/20111030230740/http://www.stumbleupon.com/su/5Fe8Ye/motherjones.com/mojo/2011/10/ows-flier-defending-against-tear-gas

#15yrsago How to make a computer that doesn’t lock out GNU/Linux https://web.archive.org/web/20120113141447/https://www.linuxfoundation.org/sites/main/files/lf_uefi_secure_boot_open_platforms.pdf

#15yrsago Microsoft buys Skype, attacks reverse engineer with bogus takedown notices and florid language https://www.phoronix.com/news/MTAwNzI

#15yrsago Justin Bieber: senator who sponsored anti-streaming bill should be “locked up — put away in cuffs” https://arstechnica.com/tech-policy/2011/10/justin-bieber-streaming-bill-author-should-be-locked-up/

#15yrsago SOPA in depth: the worst-ever copyright proposal in US legislative history? https://www.eff.org/deeplinks/2011/10/sopa-hollywood-finally-gets-chance-break-internet

#15yrsago Fresh German police-malware uncovered; everything the police said in defense to date revealed as lies https://www.ccc.de/en/updates/2011/analysiert-aktueller-staatstrojaner

#15yrsago Russia dumps daylight savings https://www.bbc.com/news/world-europe-15512177

#15yrsago Class War funnies: 1935 Daily Worker comics https://philnel.com/2011/02/02/hoff_teeth/

#15yrsago Christian groups: we will bodily protect Occupy London from St Paul’s https://www.theguardian.com/uk/2011/oct/29/christians-defend-occupy-london-protest

#15yrsago Dean of St Paul’s resigns over plan to evict OccupyLondon https://www.theguardian.com/uk/2011/oct/31/dean-st-pauls-resigns-occupy

#15yrsago The future of the living room: Authorised Domain https://dn711102.ca.archive.org/0/items/Cory_Doctorow_Podcast_215/Cory_Doctorow_Podcast_215_Authorised_Domain.mp3

#15yrsago Sales tax is still regressive, gravity still sucks, and George Osborne is still a delusional ideologue https://www.bbc.com/news/business-15519727

#15yrsago Prince Charles exercises a secret veto over a wide swath of UK legislation https://www.theguardian.com/uk/2011/oct/30/prince-charles-offered-veto-legislation

#15yrsago London cops recording movements & association with mobile tracking device: “blanket & indiscriminate” https://www.theguardian.com/uk/2011/oct/30/metropolitan-police-mobile-phone-surveillance

#10yrsago The Shadow Brokers dump more intel from the NSA’s elite Equation Group https://medium.com/@shadowbrokerss/message-5-trick-or-treat-e43f946f93e6#.x2c36nsfq

#10yrsago Wells Fargo blackballed employees who refused to commit fraud, forcing them out of the industry forever https://www.npr.org/sections/money/2016/10/28/499805238/episode-732-bad-form-wells-fargo

#10yrsago Listen: free recordings of Edgar Allen Poe stories, read by Vincent Price and Basil Rathbone https://open.spotify.com/album/6xDmRcD6sgsGbDvBRpyH5H?play=true&utm_source=open.spotify.com&utm_medium=open

#10yrsago How Minnesota’s governor performed an economic miracle by raising tax on the rich and increasing minimum wage https://www.huffpost.com/entry/mark-dayton-minnesota-economy_b_6737786

#10yrsago Icelandic women walk off the job 14% early to protest 14% pay-gap https://www.teenvogue.com/story/women-iceland-protest-gender-wage-gap

#10yrsago Snowden to journalists: your best defense is legal limits on spying, not cryptography https://medium.com/global-editors-network/e-snowden-against-surveillance-journalists-engagement-more-efficient-than-encryption-dbfbacdf9463#.jd6u431fo

#10yrsago After North Carolina Republicans banned cities selling internet, a town decided to give it away instead https://arstechnica.com/information-technology/2016/10/city-isp-makes-broadband-free-because-state-law-prohibits-selling-access/

#5yrsago LaserWriter II https://pluralistic.net/2021/10/29/norwegian-potato-flour-enchiladas/#r2r

#5yrsago Now, Put It Back! https://pluralistic.net/2021/10/31/now-put-it-back/

#1yrago The internet was made for privacy https://pluralistic.net/2025/10/31/losing-the-crypto-wars/#surveillance-monopolism

#1yrago When AI prophecy fails https://pluralistic.net/2025/10/29/worker-frightening-machines/#robots-stole-your-jerb-kinda


Upcoming appearances (permalink)

A photo of me onstage, giving a speech, pounding the podium.


A screenshot of me at my desk, doing a livecast.

Recent appearances (permalink)


A grid of my books with Will Stahle covers..

Latest books (permalink)


A cardboard book box with the Macmillan logo.

Upcoming books (permalink)

  • "The Post-American Internet," a geopolitical sequel of sorts to Enshittification, Farrar, Straus and Giroux, 2027

  • "Unauthorized Bread": a middle-grades graphic novel adapted from my novella about refugees, toasters and DRM, FirstSecond, April 20, 2027

  • "Enshittification, Why Everything Suddenly Got Worse and What to Do About It" (the graphic novel), Firstsecond, 2027

  • "The Memex Method," Farrar, Straus, Giroux, 2027


Colophon (permalink)

Today's top sources:

Currently writing:

  • “Once Is Enemy Action,” a science fiction novel about the origins of modern technofascism. Today's words: 504 (31359 total).

  • "The Post-American Internet," a sequel to "Enshittification," about the better world the rest of us get to have now that Trump has torched America. Fourth draft completed. Submitted to editor.

  • A Little Brother short story about DIY insulin PLANNING


This work – excluding any serialized fiction – is licensed under a Creative Commons Attribution 4.0 license. That means you can use it any way you like, including commercially, provided that you attribute it to me, Cory Doctorow, and include a link to pluralistic.net.

https://creativecommons.org/licenses/by/4.0/

Quotations and images are not included in this license; they are included either under a limitation or exception to copyright, or on the basis of a separate license. Please exercise caution.


How to get Pluralistic:

Blog (no ads, tracking, or data-collection):

Pluralistic.net

Newsletter (no ads, tracking, or data-collection):

https://pluralistic.net/plura-list

Mastodon (no ads, tracking, or data-collection):

https://mamot.fr/@pluralistic

Bluesky (no ads, possible tracking and data-collection):

https://bsky.app/profile/doctorow.pluralistic.net

Medium (no ads, paywalled):

https://doctorow.medium.com/

Tumblr (mass-scale, unrestricted, third-party surveillance and advertising):

https://mostlysignssomeportents.tumblr.com/tagged/pluralistic

"When life gives you SARS, you make sarsaparilla" -Joey "Accordion Guy" DeVilla

READ CAREFULLY: By reading this, you agree, on behalf of your employer, to release me from all obligations and waivers arising from any and all NON-NEGOTIATED agreements, licenses, terms-of-service, shrinkwrap, clickwrap, browsewrap, confidentiality, non-disclosure, non-compete and acceptable use policies ("BOGUS AGREEMENTS") that I have entered into with your employer, its partners, licensors, agents and assigns, in perpetuity, without prejudice to my ongoing rights and privileges. You further represent that you have the authority to release me from any BOGUS AGREEMENTS on behalf of your employer.

ISSN: 3066-764X

Read the whole story
mkalus
6 minutes ago
reply
iPhone: 49.287476,-123.142136
Share this story
Delete
1 public comment
KristenHG
10 hours ago
reply
Absolutely crucial clarification from the US Copyright OFfice on protections for human works only

EU Satellite Imagery Delayed Over Gaza and Parts of West Bank by 24-hours

1 Share

Sign up here to receive Bellingcat’s biggest investigations by email as soon as they are published. Become a member and support our work here.

Imagery captured by the European Space Agency’s freely available Sentinel-2 and Sentinel-1 satellites appears to be delayed over Gaza and parts of the West Bank, a Bellingcat analysis has found.

While the delay remains relatively short at just 24 hours, this can still impact the speed at which analysts and researchers can observe what is happening in the region.

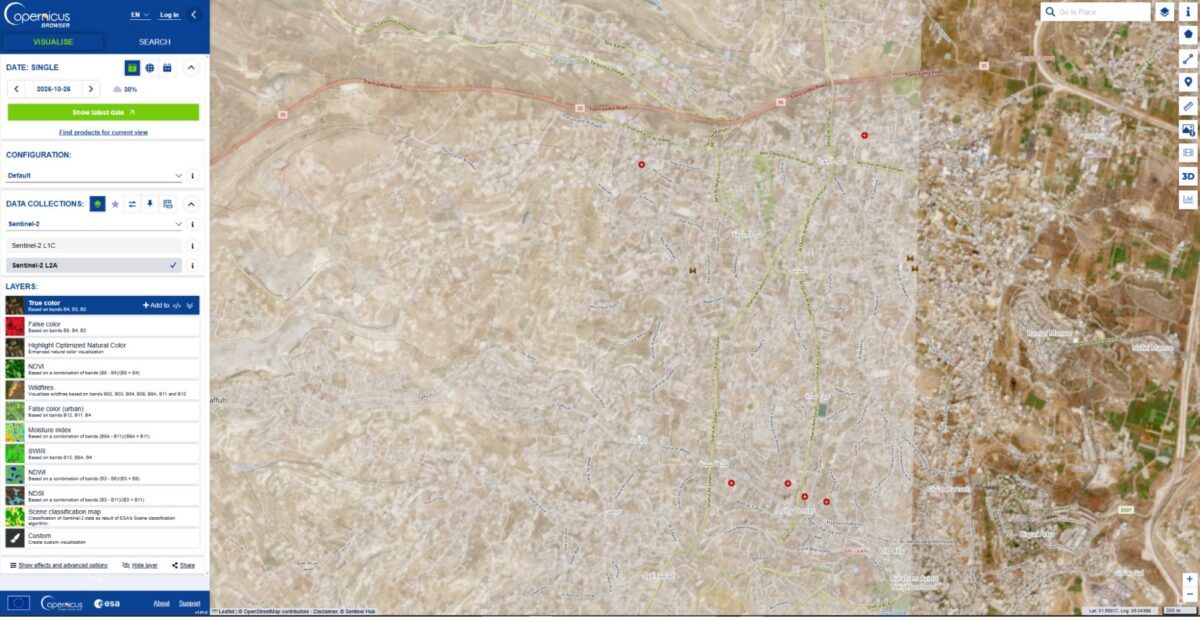
For example, the Israeli Defence Forces demolished homes in the West Bank Palestinian city of Hebron in recent days. New imagery captured on October 26, which included Hebron, would allow open source researchers to quickly confirm the demolitions, assess the impacted area and observe any unreported IDF activity. But imagery for the western half of Hebron was not available until October 27 due to the Sentinel-2 delay, inhibiting real-time fact-checking and reporting on this evolving situation.

A spokesperson for the European Union told Bellingcat that the delay was not related to events in Gaza but to “mitigate possible threats” due to the war in the Middle East “including Iran’s attacks on its neighbours and possible threats to European interests”. The delayed region of Sentinel tiles that cover Gaza as well as parts of Israel and the West Bank also extends over the Eastern Mediterranean Sea.

The European Union ordered a 24-hour delay on Sentinel satellite imagery over the Gulf of Oman earlier this year during US and Israeli strikes on Iran. However the delay impacting Gaza and parts of the West Bank has not been announced or previously reported.

“Such decisions are taken unanimously by all EU Member states and will stay in place as long as necessary,” the spokesperson said. They also said that while the Copernicus program, which includes the Sentinel satellites, operated a free and open data policy there were limitations to this for security. 

When asked if the delay, which began in late March, was related to the presence of US vessels in the Eastern Mediterranean or if there were other areas of delay, the spokesperson said they had no further comment.

Sentinel Delays

The Sentinel-2 and Sentinel-1 satellites provide an invaluable source of imagery for open source researchers. This has been especially true this year, as commercial satellite imagery providers restricted access to imagery in the Middle East, including areas of active human rights concern, such as Gaza. 

However, in July, the European Union published Council Decision 2026/1716, which ordered a 24-hour delay on Sentinel imagery over the Gulf of Oman, after a request from the US government which was involved in strikes on Iran at that time.

Just two weeks later, the European Union issued a corrigendum that unpublished decision 2026/1716 and removed it from the Council of the European Union record, although satellite data shows the delay has remained. 

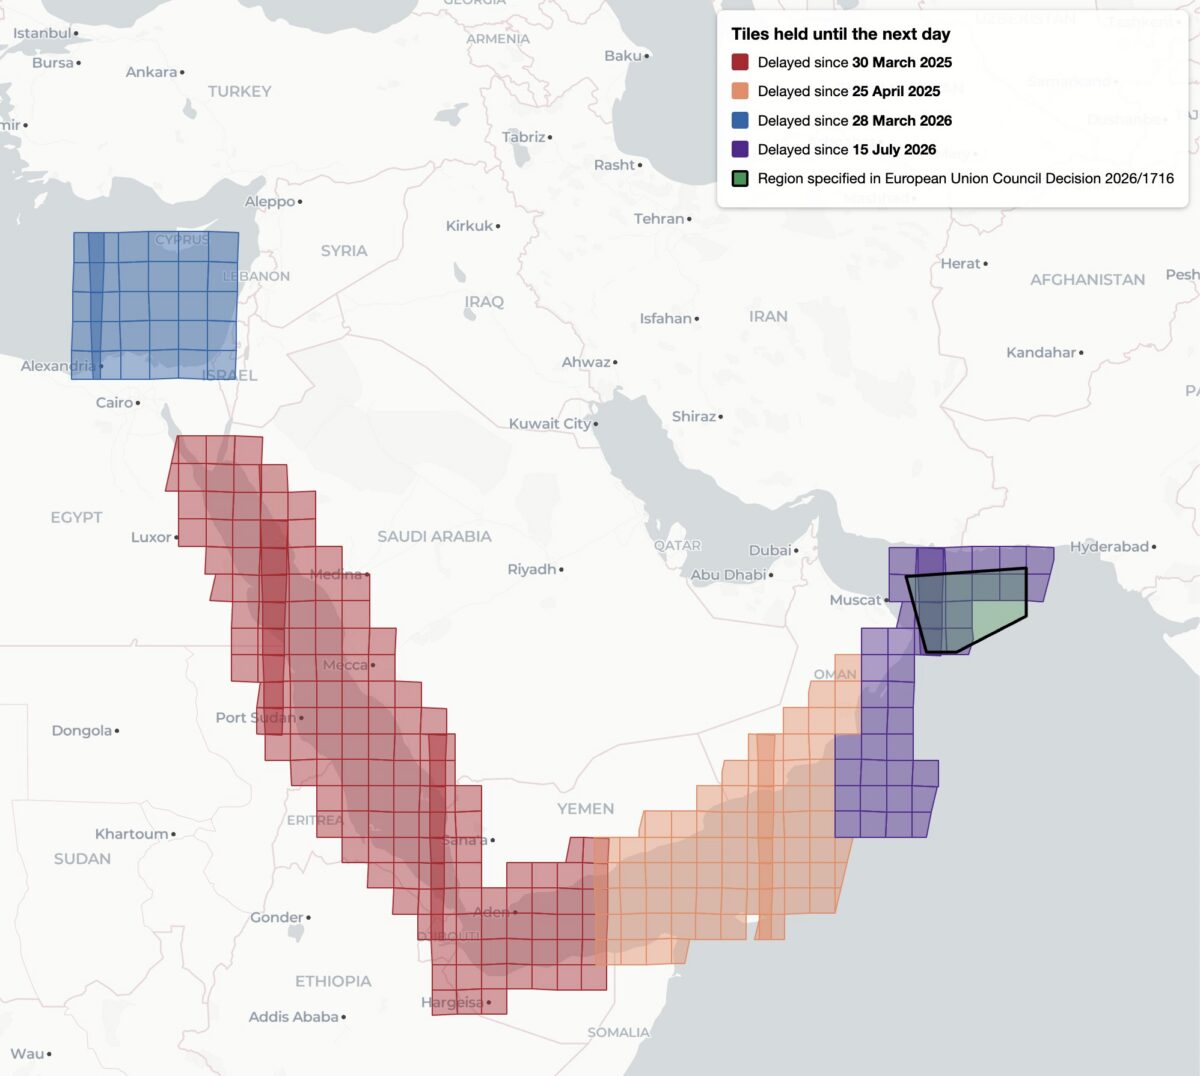
This decision, while it was available, was reportedly the first public notification of delayed Sentinel imagery. Yet it was not the first time that Sentinel imagery has been restricted, analysis shows. Bellingcat found four distinct regions of delayed satellite imagery during 2025 and 2026: the Gulf of Oman, the Gulf of Aden/western Arabian Sea, the Red Sea as well as the previously unreported delay in the Eastern Mediterranean Sea and parts of Israel, the West Bank and the entirety of Gaza.

Bellingcat’s analysis shows the regions where Sentinel-2 imagery is subject to a 24-hour delay, and when the delay was imposed. Only the July 15, 2026 delay over the Gulf of Oman was referenced by European Commission directives and the region referenced in 2026/1716 encompasses only a portion of the delayed tiles.

Bellingcat’s analysis shows that these delays have been implemented in stages. Twenty-four hour delays of Sentinel-2 imagery were first observed by open source researchers in March and April 2025 after the US launched a naval and air strike campaign against Houthi targets in Yemen. 

The previously unreported imagery delay in the Eastern Mediterranean began on March 28, 2026, the same month that commercial American space imaging company Planet Labs also restricted imagery across the Middle East. The Gulf of Oman delay began on July 15, 2026, two days after the publication of Council Decision 2026/1716.

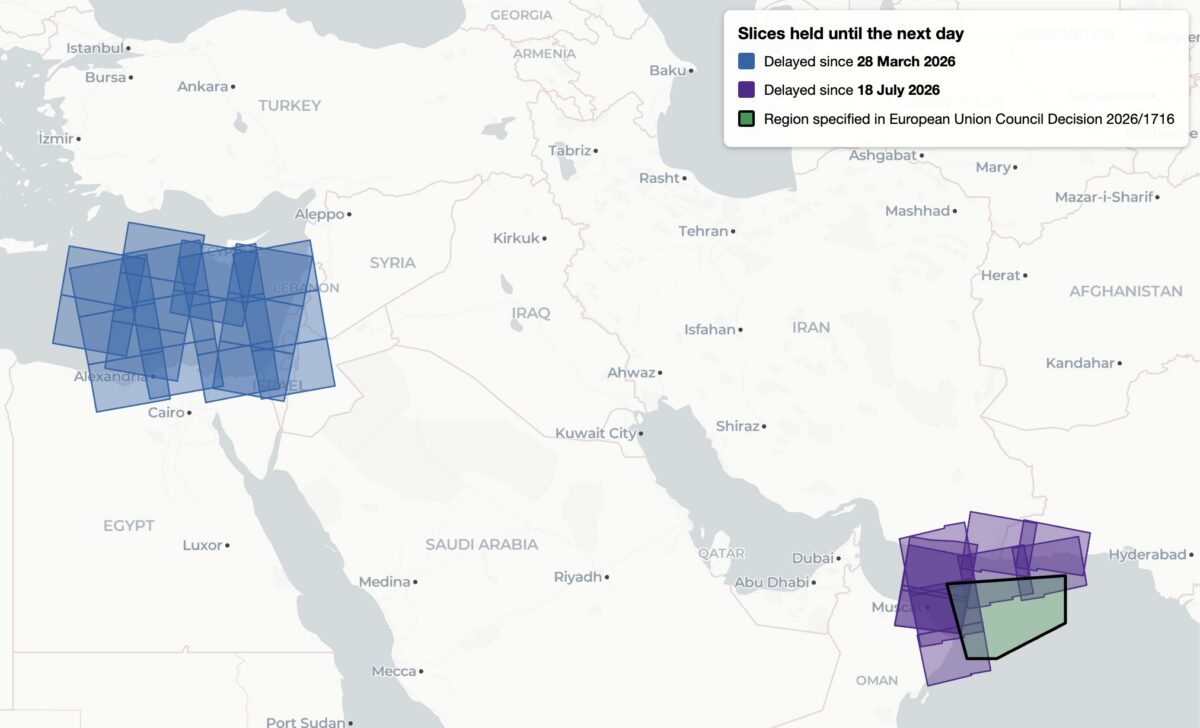
Decision 2026/1716 also specified that the delay be implemented for both Sentinel-2 and Sentinel-1 radar imagery. Bellingcat’s analysis of Sentinel-1 image availability shows that this is the case for both the Gulf of Oman region and the unreported region over the Eastern Mediterranean Sea. However, the 2025 restrictions on Sentinel-2 imagery in the Red Sea and Gulf of Aden are not implemented in Sentinel-1. 

Sentinel-1 imagery uses “synthetic aperture radar” to capture lower resolution radar images that can collect data at night and on cloudy days. This differs from Sentinel-2, which captures optical satellite imagery at higher resolution.

Bellingcat’s analysis shows the regions where Sentinel-1 satellite imagery is subject to a 24-hour delay and when that delay was imposed.

A Tale of Two Tiles

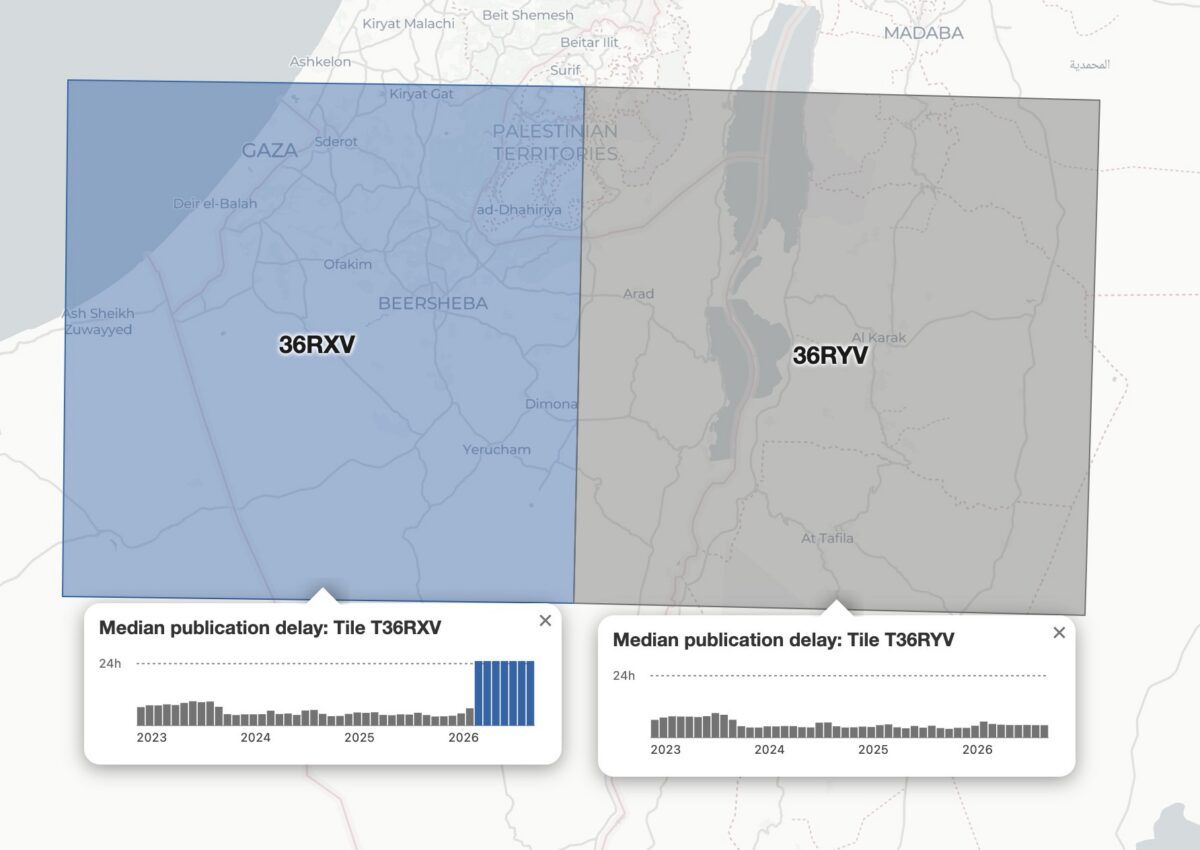
Sentinel satellite imagery is most commonly accessed by open source researchers through Copernicus Browser, a free online platform, but it is also distributed as large tiled files in the Copernicus Data Space Ecosystem. These tiles are numbered using the Military Grid Reference System, and can be listed using APIs that provide information on each tile, including the capture and publication time. By comparing the capture and publication time, the publication delay can be computed.

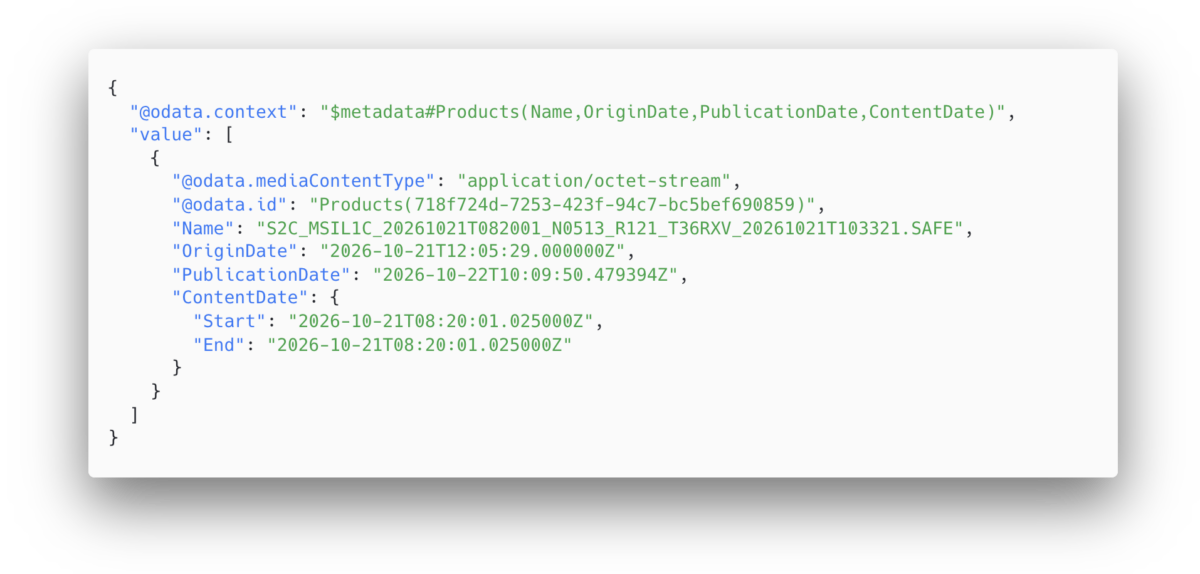
For example, the catalog information for the tile T36RXV, which includes Gaza and portions of the West Bank, Negev and Egypt, provides the following metadata for the October 21, 2026 capture.

Metadata from tile T36RXV, which includes Gaza and portions of the West Bank, Negev and Egypt.

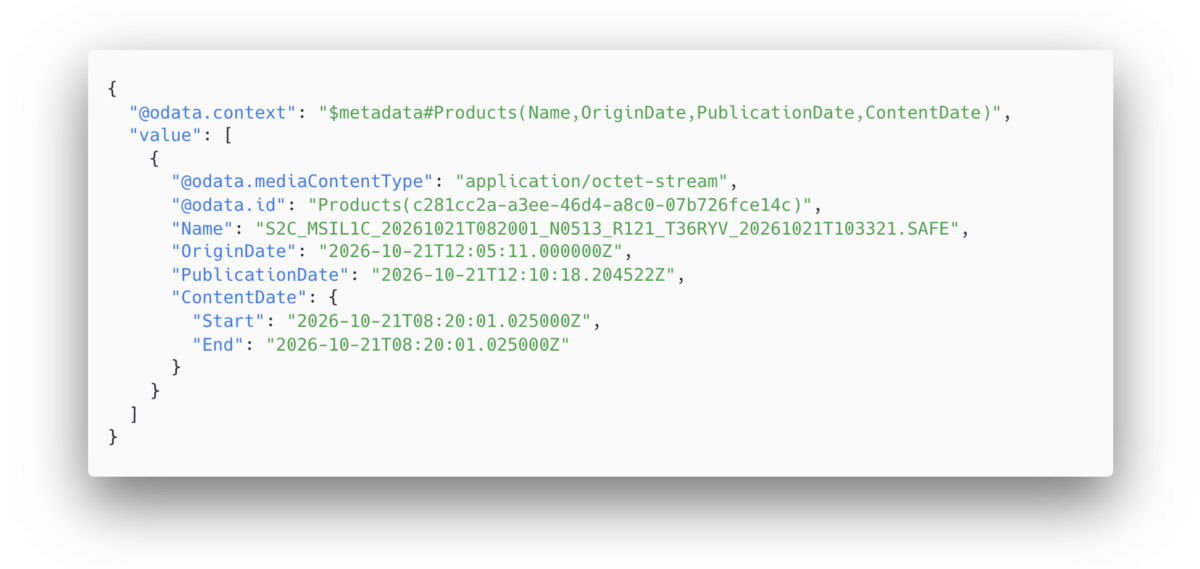
This shows that while the image was captured at 08:20 UTC on October 21, it was not published until 10:09 UTC on October 22 — almost 26 hours later. This is in contrast to the neighboring tile T36RYV, which includes parts of the West Bank, Israel, and Jordan. API data for this tile shows that the image was published at 12:10 UTC on October 21, just under four hours after the capture time.

Metadata from tile T36RYV, which includes parts of the West Bank, Israel, and Jordan.

This difference is not unique to this date either. Bellingcat’s analysis shows that this tile has been consistently delayed by one day since March 28, 2026.

Graphing the publication delay for two adjacent Sentinel-2 tiles shows a clear difference beginning March 28, 2026.

This method can be extended further, and by analysing every tile with valid publication date timestamps, Bellingcat identified all global Sentinel-2 and Sentinel-1 delays since 2023. The only consistent delays visible were those identified in the Gulf of Oman, the Gulf of Aden/western Arabian Sea, the Red Sea and Eastern Mediterranean in 2025 and 2026.

Impact on open source investigations

While the 24-hour delay on certain Sentinel imagery is a less severe restriction than other satellite providers have imposed, it can still impact the open source research process in fast moving situations. This is especially so in recent months as the European Space Agency’s Sentinel satellite data has emerged as a refuge as other satellite data is censored.

The image below shows how imagery for the eastern half of Hebron was visible on October 26, but not the western half where demolitions took place earlier this week.

The city of Hebron, Palestine, seen in Copernicus Browser on October 26, 2026. While imagery is available for the eastern half of the city, there is no recent imagery of the western half.

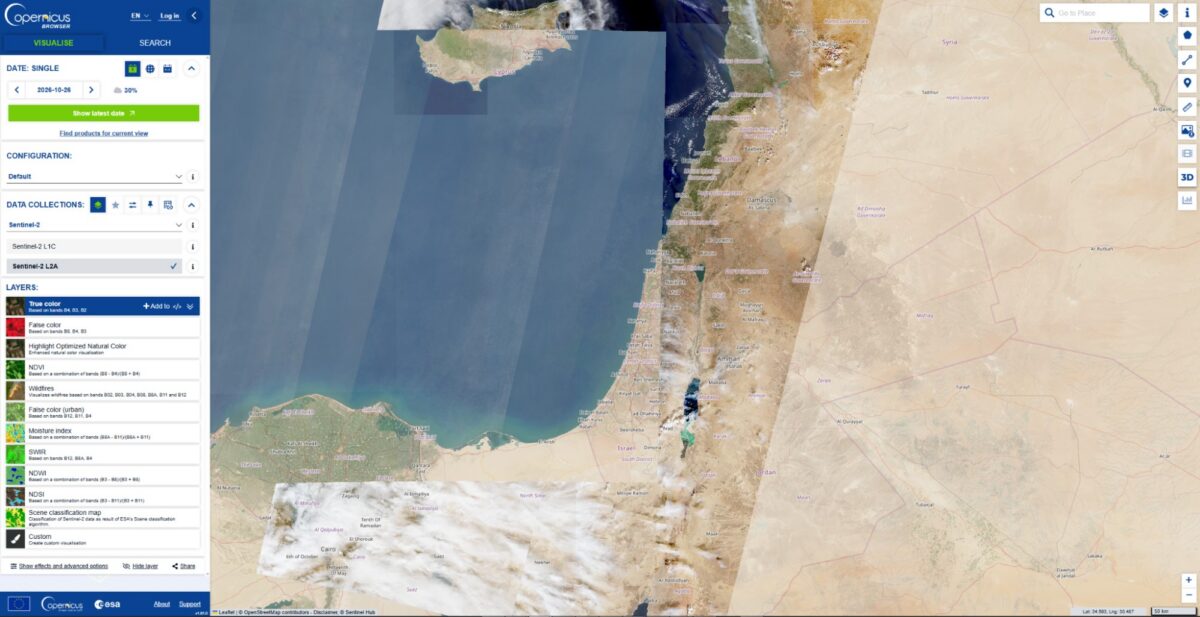
The shape of the missing tiles can be seen by zooming out within the Copernicus browser, demonstrating how imagery of Gaza and other parts of Israel and the West Bank are also delayed.

The missing tiles also include Gaza, parts of Israel, Egypt, and Cyprus, and the Eastern Mediterranean Sea.

Sentinel imagery covering western Hebron after the demolitions took place was published on October 27. However, the delay prevented local reports from being verified with satellite imagery while the situation was still ongoing.

Some Sentinel-2 users have previously described the challenges of covering fast-moving issues in the Gulf of Oman when the Sentinel delay was announced in March.


Bellingcat is a non-profit and the ability to carry out our work is dependent on the kind support of individual donors. If you would like to support our work, you can do so here. You can also subscribe to our Newsletter and follow us on Bluesky here, Instagram here, Reddit here and YouTube here.

The post EU Satellite Imagery Delayed Over Gaza and Parts of West Bank by 24-hours appeared first on bellingcat.

Read the whole story
mkalus
11 minutes ago
reply
iPhone: 49.287476,-123.142136
Share this story
Delete

Premium: Venture Capital Is Killing Itself

1 Share

Soundtrack: Spinnerette — A Prescription For Mankind

About fourteen years ago, the government made a mistake that would allow tech companies and venture capitalists to conspire to legally scam millions of retail investors, simultaneously depriving them of good information and spuriously inflating the valuations of every major tech IPO of the last 14 years.

On April 5, 2012, President Obama signed the Jumpstart Our Business Startups (JOBS) Act under the auspices of it being “too difficult” for small businesses and startups — though overwhelmingly the latter — to access capital, all while reducing reporting requirements in ways that mostly helped venture capitalists fund and startup founders run businesses in reckless and destructive ways, all sold as a good thing for society. 

In simple terms, while the JOBS Act (which was passed with rare bipartisan support) allowed companies to raise more money from more people, it also incentivized companies staying private for longer by eliminating a rule from the 60s that required companies of a certain size — above 500 shareholders and $10 million in assets — to report as if they were public.

[Editor's Note: It said "public for longer," that's now been fixed.]

Per Casual Finance: 

In 1964, Congress implemented a rule to securities law called Section 12(g)...[which] said that once a company of any real size had 500 shareholders, it had to start reporting like a public company. This acted as a trigger that pushed private companies into a public reporting regime - the same way a public company reports its financials, a private company would have to file quarterly reports, an annual report, and an update every time something big happened - which was a huge deal for startups, because startups pay people in stock. Every employee who got shares instead of a bigger paycheck was one more shareholder on the way to 500.

As Casual Finance notes, this is the rule that pushed both Facebook and Google to go public — because if you’re going to have to report like a public company, you may as well have access to the public markets:

Back in 2010, Zuck flat out said it. "We aren't planning to go public anytime soon." Then he continued by saying “I tend to think that being private is better for us right now because of some of the big risks we want to take in developing new products.

And Facebook didn't need the money. They were the hottest startup in the world and everyone wanted in…which is how, in January 2011, Facebook announced it had just raised $1.5 billion privately.

But in that same announcement, Facebook said it expected to pass 500 shareholders sometime that year. Which meant they would have to start publishing their financials "no later than April 30, 2012."

So Facebook was about to get the worst of both worlds.

They were about to have to put their numbers out in the open for every competitor to be able to read, just like a public company. Without any of the upside of actually being a public company. Like a large infusion of equity capital and having liquidity for your stock.

So in 2012, Facebook took their stock public.

The JOBS act, amongst other changes, made it so that you could have up to 2,000 shareholders (but no more than 499 “unaccredited” investors) and, crucially, changed the rules so that employees were no longer counted in the calculation, effectively removing any chance that most startups would ever have to deal with reporting like a public company ever again.

The rationale was that having to report like a public company required audited accounts, adding an "unnecessary burden” to fledgling companies, even though “fledgling” here meant “companies worth hundreds of billions of dollars on paper” that absolutely could afford an auditor. Those pushing for the bill also believed that these requirements unfairly punished companies for awarding stock grants, and that public reporting was tantamount to “exposing trade secrets,” as if there was literally no amendment that could’ve been made to anticipate these problems other than “removing reporting anything of any sort.”

However minor this change might have seemed at the time, the net result was one of the largest private valuation bubbles in history, because there was (and is) no longer any incentive for a company to go public before it’s “ready,” with “ready” defined as “as much value has been drained from the company as humanely possible.”

As Casual Finance noted, when Microsoft went public, it had a market cap of around $500 million, Google $23 billion, and Facebook $100 billion, with their total market capitalization as of writing this sentence sitting at around $10.29 trillion. Anyone investing in any of these IPOs in the first five to ten years of their existence had a chance to multiply their money, because you were able to invest before the companies became massive multiconglomerates with multi-trillion dollar market caps, in turn creating value for millions of households that “took the risk” on investing on an earlier-stage company.

These three companies are used as the poster children of why you should invest in a new tech stock — that you’re getting in on the ground floor, with the reward for the risk being that you’d have the chance of a massive multiple.

Except that doesn’t really work if the companies wait as long as humanly possible to go public.

The reason that Microsoft, Google, Meta, Amazon and all the other famous names in “big IPOs that made early investors a lot of money” was that they had to go public before they’d reached the height of their valuation. 

And crucially, their valuations are decided by market forces which, while deranged and emotional, at least are somewhat guided by the underlying financial picture of the company.

Today’s startups have their valuations defined entirely based on the whims and fancies of a venture capital sect that makes up a multiple they’re comfortable investing at. That’s how Instinct, a zero-revenue “AI agent” that you text to do stuff, is somehow worth $10 billion — because investors from Sequoia Capital, Benchmark, and Coatue had been willing to give it $1 billion for 10% of the company. 

These inflated valuations drain the vast majority of potential opportunity that any investor might have, effectively transferring all the risk for the company’s future onto the public markets while offering very little in return. The days of thousand-percent-or-more returns are long dead, despite every single IPO selling itself on this eventuality, like SpaceX did when it proposed it had a $28.5 trillion total addressable market. 

Anthropic’s upcoming IPO has the company demanding a $2 trillion valuation, equivalent to both Meta and SpaceX, based on flimsy promises of $200 billion in annual revenue years in the future and a $30 trillion total addressable market. It is, to quote New Constructs, presenting risks and is positioned to be a far bigger ripoff of the US capital markets, and exists only as a liquidity mechanism so that early investors can multiply their dodgily-valued early investments by selling their shares under the scummiest possible terms.

Anthropic and OpenAI’s IPOs pose a genuine threat to any investor that dares entangle themselves with unprofitable, unsustainable AI companies promising the world (or the world’s destruction), all sold under the auspices of potentially buying into the next Facebook, Google or Microsoft. In reality, the kind of growth you’d need from these companies to reach anything close to the returns of those early-stage tech investments would require them to have trillions of dollars a year in revenue and market capitalizations of $20 trillion or more — an impossibility that nobody seems to want to discuss.

Yet these rotten incentives have also led to a massive valuation bubble in startup valuations writ large, with the AI bubble being the inevitable result.

By allowing private companies to avoid the reporting strictures of the public markets, financial regulations incentivize a kind of venture welfare, keeping companies that cannot borrow money or otherwise sustain themselves through cashflow — you know, bad companies — alive for longer than is natural, never forcing them to become real companies that can survive, with every trip to Sand Hill Road bumping the valuation up further, making any IPO or acquisition much harder to stomach.

This wasn’t as much of a problem when venture capital was pumping up software companies and flogging them to the markets or dimwitted private equity firms, but has become a critical situation for the legions of cashflow-negative AI companies with aggressively-inflated valuations. 

In a pre-JOBS environment, many of these companies would’ve wilted in sunlight, and, I’d argue, been forced to run businesses that could stand on their own two feet. Instead, as I discussed in last year’s Enshittifinancial Crisis, these companies are more venture-dependent than any other hype cycle in history, and because venture is so excited about the potential, they’re investing at bigger and bigger rounds, creating the largest valuation bubble in the history of technology, including the Dot Com Bubble.

Today I am going to aggressively advocate for reforms — if not an outright repeal — of the JOBS act, and call for serious legislative efforts to bring the private markets to heel.  

My argument is simple: the current system is built to incentivize rich and powerful people inflating private assets with spurious valuations, harming retail investors, reducing the available capital to good startups, and incentivizing the continued development of bad, unsustainable companies. Venture is no longer a trustworthy vehicle for investment, nor can venture capitalists be trusted to value startups any further.

The JOBS act did the literal opposite of what it intended to — fewer tech companies went public, and those that went public did so at oversized valuations pumped up by venture capital, using retail investors as exit liquidity under the flimsy pretense of “getting in on the ground floor.” We are placing outsized trust in a handful of extremely rich and disconnected people and their ability to pick winners, despite the fact that the majority of venture capitalists are fucking terrible at doing so.

For over a decade, venture capital has inflated the value of startup after startup, then been surprised again and again as these companies didn’t work out, with the vast majority of “successes” — SpaceX, Snap, Airbnb, and Uber — mostly existing to dump their horrid bags on an unsuspecting public.

And by repeating the same cycle — inflating companies based on hype and ever-growing valuations — venture capital is setting itself up for a collapse.

Today I’ll explain how it’s happening, and how we might fix what’s left in the end.

Read the whole story
mkalus
13 minutes ago
reply
iPhone: 49.287476,-123.142136
Share this story
Delete

Scientists Analyzed Thousands of Psychedelic Trips. They Found Something Disturbing

1 Share
Scientists Analyzed Thousands of Psychedelic Trips. They Found Something Disturbing

Researchers have amassed a trove of more than 25,000 calls to a support hotline for people during and after psychedelic trips, making it “the largest dataset of psychedelic support interactions ever assembled—exceeding the combined sample sizes of all published psychedelic clinical trials by an order of magnitude,” according to a study published on Friday in Science Advances.

Despite the popularity of psychedelics as recreational drugs, and increasing interest in them as medically-prescribed therapeutic treatments, there is very little research about the effects of these substances outside of clinical settings with carefully-selected patients. That, scientists say, is limiting what we can learn about the effects of these drugs, because the vast majority of psychedelics are consumed by all kinds of people in homes, festivals, ceremonial gatherings, or other uncontrolled environments.    

The Fireside Project, a nonprofit founded in 2020, has filled this knowledge gap with its Psychedelic Support Line, which connects callers who are on bad trips, or who are seeking more information about psychedelics, with trained volunteers who offer confidential peer support. 

🌘
Subscribe to 404 Media to get The Abstract, our newsletter about the most exciting and mind-boggling science news and studies of the week.

The team has now published a compendium of 25,419 anonymized interactions with 220 hotline volunteers that took place between April 2021 and February 2026. The database opens an unprecedented window into the experiences of people on psilocybin, ketamine, MDMA, LSD, ayahuasca, and even cannabis, which is not generally considered a psychedelic but can trigger similar effects, such as mild hallucinations. 

It’s a “treasure trove,” said Félix Schoeller, a senior research scientist at the Institute for Advanced Consciousness Studies, a California-based nonprofit, who led the study, in a call with 404 Media. “In general, we're really lacking any evidence and data beyond what exists in the underground world, if you will, for psychedelic therapy.” 

“There's different types of knowledge,” continued Schoeller, who is CEO of ReWire Neurotechnologies, a startup focused on novel experiential treatments for depression. “Some cultures and communities have been doing that for thousands of years. But there's a question about how to do this in a way that follows the principles of biomedical science.”  

The interactions included phone calls and text exchanges with hotline volunteers who provided support by talking through the experience or connecting callers with emergency services in the most urgent cases. About 40.2 percent of callers (10,208 interactions) were actively tripping, while 32.1 percent of callers reached out after they had tripped, a period known as “integration.”  

The rest of the calls fell into smaller categories, such as informational inquiries about certain substances, requests to prepare or buy drugs, or calls from “trip-sitters” assisting a person on psychedelics. 

Psilocybin was the most commonly reported substance (9,348 callers), followed by LSD (2,247callers), cannabis (2,004 callers), and ketamine (1,194 callers), and MDMA (682 callers), with ayahuasca and other drugs logging much smaller numbers.  

Surprisingly, callers who had used cannabis  reported the highest distress rate—47.2 percent had bad experiences with the drug. Though cannabis has a reputation as a low-stakes substance, the study confirms that it can induce real distress in some cases that warrant consideration for harm reduction. The distress rates for the rest of the commonly used psychedelics were only slightly lower than cannabis, ranging between 40 to 42 percent.

The study also revealed 43 rare but disturbing instances of “facilitator abuse,” including at remote retreats or ceremonial gatherings involving ayahuasca. In these cases, callers reported abuse from the people providing psychedelics, such as reports they had deliberately been given extra doses without consent. 

Those reports “provide the first quantitative documentation of this phenomenon in a community help-seeking sample,” according to the study. “The pattern of these reports—clustering in ceremonial settings involving plant medicines, presenting primarily as trauma-processing calls, and involving callers with elevated rates of prior PTSD diagnoses—suggests that even modest surveillance through existing peer support infrastructure can detect harm occurring in unregulated psychedelic settings.”

Some calls also came from people who said they suffered from schizophrenia, or had taken multiple psychedelics, offering a rare glimpse of situations that could not be observed in clinical settings. 

“This kind of data can inform us on these topics in the context of legalizing these drugs and making them accessible,” said Schoeller. “I'm glad that there's this data that exists that people can look into to support or contradict the claims that they make as to how these things should be done.” 

The study also outlines several limitations, including its sample bias of people who are inclined to call a hotline in the first place—which is not representative of psychedelic consumers at large—as well as self-reported accounts of doses, among other factors that are impossible to verify.

Despite the noisiness of the data, however, it contains helpful clues about avenues for future research. In Schoeller’s view, one of the most important revelations was that the success of a call was strongly linked to the perception that the hotline volunteer showed genuine care and empathy toward the caller. Using 2,777 postinteraction satisfaction surveys, the team found that the few negative experiences with the hotline tended to stem from feelings that the volunteer was dismissive, or didn’t seem to care about the caller. 

“My takeaway is that the number one thing that predicts whether a support call will not work” is “the volunteer being perceived as genuine,” Schoeller said. “That's something that, in many ways, poses a problem to the biomedical system of centralized hospitals. I'm not trying to be ideological in any way, but when you create a centralized institution where you throw everybody to a single place to get care”  then “clinicians become burned out.”

For this reason, Schoeller and his colleagues plan to follow up on the role of perceived care and empathy in treatment, and to emphasize this factor in guidance for community-based peer support for people in crisis due to psychedelics. It also reinforces the value of the Fireside Project’s hotline, which provides a safe and confidential service for people who might be reluctant to contact emergency services because of the criminalization of these substances or fear of incurring medical debt.

“For many people, they have experiences with psychedelics, and they may not be required to go to the ER, but they still need someone to help them navigate the difficult experience,” Schoeller concluded. “The hotline can truly be a lifeline for them.” 

Read the whole story
mkalus
17 minutes ago
reply
iPhone: 49.287476,-123.142136
Share this story
Delete

Proton’s CEO Cancels AI ‘Re-Interviews’

1 Comment and 3 Shares
Proton’s CEO Cancels AI ‘Re-Interviews’

On Friday, Andy Yen, the CEO of Proton, cancelled a series of nearly company-wide ‘re-interviews’ that would have forced employees to explain how they are using AI, with the clear intention that they may be fired if not using it enough in the eyes of Proton leadership, according to six current Proton employees and audio of an around two hour all-hands meeting obtained by 404 Media.

The move came after 404 Media published an investigation on Thursday, which showed how Yen was aggressively pushing AI across Proton, in some cases despite security concerns from employees. In one exchange, an employee in the company’s security Slack channel urged Proton to at least take a few days to pentest newly written code before pushing it live. “That’s bullshit and loser thinking. Of course it’s possible to be fast and secure,” Yen wrote in the channel at the end of August. “Stop thinking always of how to be slower, and focus more on how to be faster.” Yen added, “stop lovingly handcrafting all our code and use AI more.”

The re-interview cancellations likely don’t address the concerns of many Proton users, who are more focused on Proton’s deprioritization of security; many Proton users have blasted the company’s leadership on social media over the last 24 hours and explicitly called for Yen to resign.

The investigation was based on conversations with eight current and one former Proton employees, Slack chats, meeting audio, and an AI manifesto written by the company’s CTO Bart Butler. It painted a picture of Proton that is very different to the public’s perception of a company carefully protecting privacy. Instead, Proton is barreling ahead with AI in large part to achieve more annual revenue. The investigation also found a culture of fear across Proton, where employees have genuine concerns about security or being asked to develop security-focused products with AI, but feel unable to voice them because Yen mocks or insults employees in front of everyone else.

“I don’t think he will change anything, and I think the only reason we had this meeting is because he has a rebellion on his hands,” one employee told 404 Media after the all-hands meeting on Friday.

Near the start of the meeting, Yen said, “I want to acknowledge myself, personally, that there was a communication failure on my part and there are many things that probably could and should have been communicated differently, and this is something that I’ll have to reflect on and improve over time. So I will do that.”

“So what does that mean going forward? Going forward, I'm still going to push,” he added.

Yen said leadership gathered in the last couple of days to talk about the re-interviews, and spoke to the Proton board too. “They’re closely monitoring the situation,” Yen said. (Proton is owned by the Proton Foundation, whose board of trustees includes Yen, Sir Tim Berners Lee, Prof. Carissa Veliz, Dingchao Lu, and Antonio Gambardella.) 

After those discussions with leadership and the board, “We’ve decided to actually cancel the re-interviews,” Yen said. “Why? Well, I think actually in a, let’s say, unintentional way, they have actually already served their purpose.” As in, employees are now talking and learning about AI.

💡
Do you know anything else about Proton? I would love to hear from you. Using a non-work device, you can message me securely on Signal at joseph.404 or send me an email at joseph@404media.co.

Yen also mentioned “org changes,” and said that part of this is “redistributing talent across teams.” He said that the reorganization will happen next month, “but there will be no loss of jobs from AI.” 

Later in the call, Butler said Yen “needs to, and he has committed to, doing better” regarding how he communicates with his employees. “Using AI effectively and pragmatically does not mean that we’ve given up on security, or good architecture, or sound software engineering principles,” he added.

“We fucked up, we know we fucked up,” Butler later said in response to an employee’s comments in the meeting.

“Your old job is gone,” Butler’s AI manifesto, posted to Slack, told engineers, 404 Media reported on Thursday. He wrote that not embracing AI posed an “existential threat to the success of the mission itself.”

Reactions to the re-interview cancellations were split across the Proton employees 404 Media spoke to. One said, “Some are happy as it’s progress. Others believe that this won’t change anything because there isn’t any consequence for Andy [Yen].” The employee added they “would have preferred real accountability from the leadership team.” They said they felt not much could have happened due to Yen having the majority of Proton’s shares.

Another employee said, after Proton canceled the re-interviews, “They said in the next breath they want to continue pushing AI and that the things that were to be measured in the re-interviews would become a component of the performance reviews.”

“They have said clearly the direction had not changed. As a Proton user that doesn’t reassure me,” the employee said. “As an employee, the re-interviews weren’t cancelled until this became public despite concerns raised by many of us. I think it goes beyond communication issues and growing pains.”

“Right now, everything seems consistent with it being damage control,” they said. 

Another employee said they were “mostly happy with how this was addressed including by Andy [Yen].”

Proton did not respond to a request for comment.

After 404 Media published the investigation on Thursday, Yen took to Reddit. Users downvoted his response more than 1,200 times. Many Proton users on social media said they were cancelling their paid Proton plans.

Read the whole story
mkalus
20 minutes ago
reply
iPhone: 49.287476,-123.142136
Share this story
Delete
1 public comment
angelchrys
2 days ago
reply
I think I'll still be cancelling
Overland Park, KS

Proton Mail goes full AI slop, Tuta starts going AI slop

1 Comment

Proton does email and documents and a VPN and, ahaha, a chatbot. Proton’s pitch has always been security and privacy. That is their product.

Proton CEO Andy Yen has gone full chatbot — and it’s eaten his brain. [404, archive]

Here’s Yen on how much Proton engineers should test their code for security:

That’s bullshit and loser thinking. Of course it’s possible to be fast and secure.

… stop lovingly handcrafting all our code and use AI more.

If you’ve ever coded anything where security is a requirement, I’d hope you’re boggling at that. But Yen has fully replaced his brain with a clockwork mouse:

Proton installed software on workers’ computers that track how much AI code the company is generating; and Yen said this is the last year that Proton will hire engineers at all, and instead only hire people to build things with AI.

Employees have been leaking furiously to 404:

a culture of fear inside Proton, where many employees are hesitant to even mildly critique Yen’s views or discuss engineering problems.

… “The CEO is in full AI psychosis and has been for a while now,” one of the sources told 404 Media.

Privacy is merely a talking point for marketing. The internal concerns are velocity and revenue:

barreling ahead with AI as quickly as possible so it can achieve the explicit goal of more annual revenue.

One employee asked Yen: how do you keep security when you’re doing AI coding? Yen berated him:

The employee “is saying his usual bs of we can do it but we will be even slower than we are today and I’m saying only losers think like that,” Yen wrote, adding that workers should prompt “better.”

It can’t be that stupid, you must be prompting it wrong!

In May, Proton announced a move to post-quantum encryption. That’s good! But it won’t re-encrypt older emails immediately. Now, that should be fine.

But Yen was really upset at one discussion on Reddit in particular. He told his staff to get on the socials and fix it: [Reddit, archive]

So go on there with your personal account and comment to set the record straight. Perception is more important than truth, the truth doesn’t matter if you don’t win on perception.

If you’ve ever been in an online discussion of Proton, you’ll have seen fanboys who post like weird shills. These may well have been literally Proton employees, shilling because their boss ordered them to.

Pivot to AI was calling out Proton’s AI nonsense as far back as July 2024. We got an earful from ardent Proton fans, some of who may not have been literally employees. Who knows? Amy and I look forward to their apologies. Any day now.

Trusting Proton is trusting an AI-addled CEO who is cutting any corner he can to save a buck. Security is job number three at best. Where do you go now for secure email?

For a long time, the answer was Proton’s main competitor, Tuta, formerly Tutanota.

Tuta does a lot of marketing opposing the idea of having AI anywhere near your email. For example, this one from 2024: [Mastodon, archive]

We’re not interested in diving into the AI or crypto hype. It is important to us as a  company and as global citizens to put ethics above profit, that’s why we are not pursuing AI integration or built-in crypto features.

In Tuta’s 2025 user survey, only 3% wanted “an AI copilot.” [Tuta, archive]

Tuta regularly posts against the AI vendors. How to leave ChatGPT. Gemini invades your privacy and you should de-Google. Meta’s new Muse bot only wants your data. How to remove Copilot from Windows. [Mastodon; Mastodon; Tuta; Mastodon]

Tuta’s contribution policy for code is explicitly against AI: [Github, archive]

This project does not accept contributions or bug reports produced, in part or in full, with assistance of large language models (LLMs)/generative AI. Maintainers will close issues or delete comments without further explanation if they suspect that any part of the issue is generated.

Unfortunately, Tuta have started coding with a chatbot anyway. Someone asked about this on Tuta’s GitHub. Here’s their excuse: [GitHub, archive]

Internal use is different because whoever is committing LLM-assisted code takes full responsibility for it and is therefore staking their reputation on that code being good. Git blame will also still show their name.

Tuta used dislike for AI as a marketing point for years, they put a no-AI policy on their codebase — and then they went chatbot anyway.

Now Tuta’s acting surprised their paying customers see this as a rugpull.

What about that anti-AI contribution policy? [Mastodon, archive]

This is because we are in the exploring phase, and we haven’t decided if/how to use AI exactly. We need to get this evaluated first internally before we can update the contribution policy. I hope you understand.

Yeah, we understand. Why are they doing all of this? Here’s Hanna from Tuta: [Reddit, archive]

The goal of Tuta is to bring privacy to everyone and for that the Tuta apps must become much more feature-rich and competitive with Big Tech equivalents (eg Gmail).

Velocity and features again. Security is job number three. But don’t worry:  [Mastodon, archive]

The current Tuta apps are built more than 99% without AI

Your security system is 99% not made of chocolate gear wheels!

A security company that uses chatbots for anything does not care about security. AI to get velocity is not compatible with security.

So who’s left? Fastmail are encouraging AI users with an MCP server. [Fastmail]

Also, Fastmail are union busters. They fired most of a union bargaining unit in 2024. Fastmail said this was just a restructuring. One that just happened to mostly fire the union organisers. Coincidence, I’m sure. [Mastodon, archive]

So David, who do I use for my email now, huh? I can’t advise you on secure email. I’m still living on GMail, who are a known evil.

But if you use a service, you’re trusting those guys. And you need to be ready to jump in a moment if they go bad.

Security is not a product you can buy in a box. It’s an ongoing process.

Or you could pivot to small rocks and twigs. It’ll be a lot less stress.


It’s pledge week at Pivot to AI! Please put in your $5 to keep us going! It really helps!

Read the whole story
mkalus
25 minutes ago
reply
Yeah well, just migrated all my stuff over.

I really do not want to have to string my own Cloud storage / Email server, I already have a job. *sigh*
iPhone: 49.287476,-123.142136
Share this story
Delete
Next Page of Stories